Large language models are trained on the public internet, not on your company’s policies, contracts, or customer records. Ask a plain LLM a question about your leave policy or your latest product catalog and it will either admit it doesn’t know — or worse, guess. AI-RAG (Retrieval-Augmented Generation) is how Herbie.AI closes that gap, and it’s one of the platform’s most important capabilities for enterprises that need answers grounded in their own data.
As IBM explains, retrieval-augmented generation extends what a language model can do by connecting it to an organization’s own structured and unstructured data, instead of relying only on what the model memorized during training. Here’s how Herbie.AI’s AI-RAG works, end to end, as one layer of the wider Conversational AI Engine.
What Is AI-RAG?
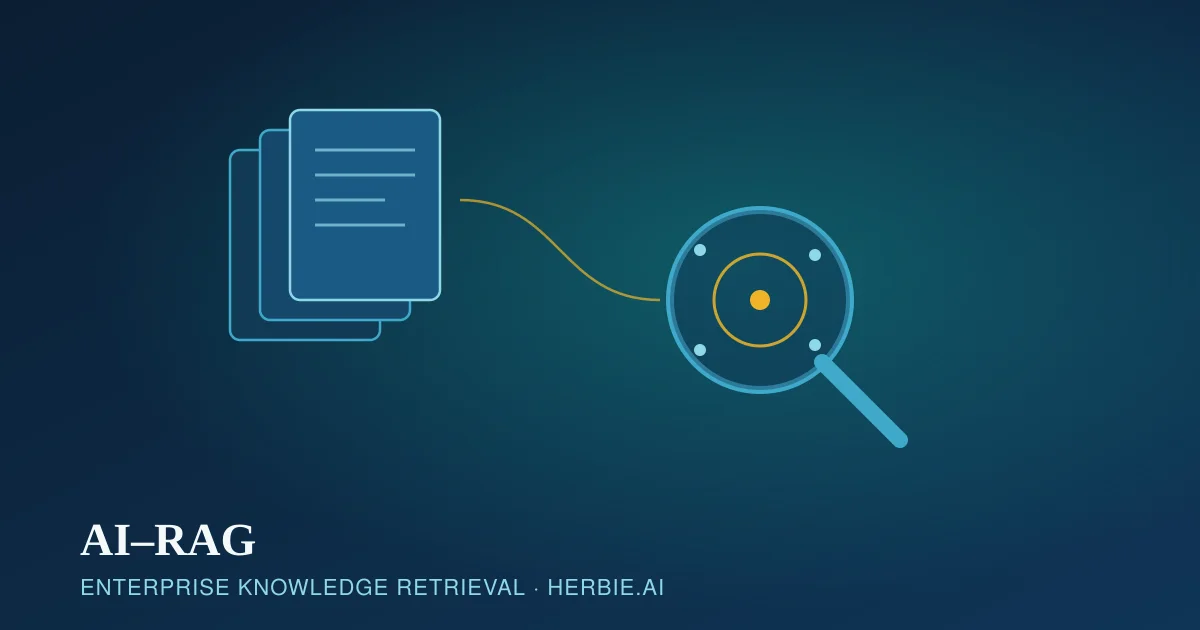
AI-RAG is an architecture that improves an LLM’s answers by retrieving relevant information from enterprise knowledge repositories before generating an answer. Instead of relying solely on the model’s internal training, Herbie.AI runs a semantic search across approved organizational content and supplies the most relevant material as context for the AI. A standard LLM goes straight from question to generated answer; an AI-RAG pipeline inserts a semantic search and knowledge-retrieval step in between, so the final answer is grounded in your own documents rather than the model’s general training data.
Why AI-RAG Matters for the Enterprise
Organizations hold valuable information across documents, databases, knowledge bases and internal systems. AI-RAG is what lets Herbie.AI actually use it:
- Improves response accuracy
- Reduces hallucinations
- Provides organization-specific answers instead of generic ones
- Supports compliance requirements
- Keeps responses aligned with current policies
- Removes the need for static, hand-maintained FAQs
- Enables rapid knowledge updates without retraining the AI model
Where Herbie.AI’s Knowledge Comes From
Herbie.AI can ingest knowledge from a wide range of enterprise repositories, so AI-RAG isn’t limited to a single document type:
| Source | Examples |
|---|---|
| Documents | PDF, Word, Excel, PowerPoint |
| Websites | Corporate portals, product pages, documentation sites |
| Knowledge bases | Internal documentation, FAQs, SOPs |
| Collaboration platforms | SharePoint, Confluence, Google Drive |
| Databases | SQL Server, PostgreSQL, Oracle, MySQL |
| CRM & ERP | Customer records, product catalogs, transaction data |
| File shares | Network folders, NAS storage |
Inside the Knowledge Ingestion Pipeline
Turning raw enterprise content into AI-searchable knowledge happens in stages: document collection, parsing and extraction, cleaning and normalization, chunking, embedding generation, and finally loading into a vector database that is search-ready. Each stage exists to make the knowledge more accurate, more searchable, and better optimized for retrieval.
The parser extracts text, tables, headings, metadata, hyperlinks, lists and captions from PDF, DOCX, XLSX, PPTX, CSV, TXT, HTML, Markdown, XML and JSON files. Before anything is indexed, the platform removes duplicate text, normalizes whitespace, standardizes character encoding, strips irrelevant boilerplate, and identifies the document’s language — because clean input data is what makes AI-RAG retrieval reliable in the first place.
Chunking, Embeddings and Semantic Search
Large documents are split into smaller, meaningful chunks so the AI can retrieve just the relevant section instead of an entire 150-page handbook. A single Employee Handbook, for example, might be split into Introduction, Leave Policy, Travel Policy, Expense Policy, Benefits, Code of Conduct and Security Guidelines — with each section becoming multiple searchable chunks using fixed-size, sentence-based, paragraph-based, section-aware or semantic chunking, depending on the document.
Each chunk is then converted into a numerical embedding that captures its meaning, not just its exact wording. That’s what lets Herbie.AI answer “Can I work remotely while traveling?” correctly even when the source document actually says “temporary remote work during business travel.” Traditional keyword search looks for exact words; semantic search looks for similar meaning — so “How many vacation days do I get?” correctly matches the Annual Leave Policy, and “Can I claim hotel expenses?” correctly matches the Travel Reimbursement Policy.
Before any result reaches the language model, it’s re-ranked based on semantic similarity, metadata relevance, the requesting user’s permissions, document freshness, confidence score and business priority, then added to the model’s prompt as retrieved context. Only after that grounding step does Herbie.AI generate its final answer.
Metadata: What Makes a Chunk Governable
Every chunk carries metadata that makes it both easier to find and easier to govern — document name, department, version number, author, creation and expiry dates, language, and access level. A Leave Policy chunk tagged version 4.2, Human Resources, Internal access is what lets Herbie.AI confidently prefer it over an older draft, restrict it to the right audience, and flag it for review once its expiry date passes.
How Retrieved Context Actually Reaches the Model
Once the right chunks are found and re-ranked, they’re inserted directly into the prompt sent to the language model, alongside an explicit instruction to answer only from approved enterprise knowledge. A simplified version looks like: system instructions telling the model to answer only using approved enterprise knowledge, followed by the retrieved context — say, Leave Policy v4.2, HR Circular 2026-01, and the Employee Handbook — and finally the user’s actual question, such as “Can unused annual leave be carried forward?” That structure is what keeps the model’s answer grounded in the organization’s real, current policy rather than a plausible-sounding guess.
The Knowledge Lifecycle Behind Every Answer
Content that AI-RAG retrieves doesn’t appear from nowhere — it follows a controlled lifecycle: create, review, approve, publish, index, retrieve, monitor, update, and eventually archive. Keeping every stage auditable is what lets an organization trust that whatever Herbie.AI retrieves was actually reviewed and approved, not a stray draft that happened to be sitting in a shared folder.
Reducing Hallucinations With Grounded Answers
Hallucinations happen when an AI generates a plausible-sounding but incorrect answer. Herbie.AI reduces this risk through enterprise knowledge grounding, retrieval confidence thresholds, response validation, source prioritization, optional citation support, and human review workflows for sensitive domains. If no reliable information is found, the platform is designed to say so rather than invent an answer — which matters just as much for better business decisions as it does for user trust.
Governance: Access Control and Knowledge Quality
Not every user should see every document, so Herbie.AI supports role-based retrieval — an employee might retrieve HR policies and IT guides, while only Finance can retrieve financial procedures and only HR can retrieve employee records. The AI should never surface information a user isn’t authorized to view. On top of access control, AI-RAG performance depends on ongoing governance: assigning document owners, defining review schedules, archiving obsolete content, maintaining version history, and monitoring which documents actually get retrieved. Learn more about how RAG AI helps businesses make better decisions once that governance is in place.
AI-RAG Across Industries
- Human Resources — employees ask about leave, benefits, payroll and policies
- Banking — customers retrieve loan, account and product information
- Insurance — agents access underwriting guidelines and claim procedures
- Healthcare — staff retrieve clinical protocols and administrative policies
- Manufacturing — technicians access equipment manuals and maintenance procedures
- IT service desk — employees retrieve troubleshooting guides and documentation
Getting the Most Out of AI-RAG
AI-RAG performs best when the underlying knowledge is well organized: use clear document headings, avoid scanning poor-quality PDFs when a digital copy exists, maintain a single authoritative version of each document, review frequently accessed content regularly, and archive obsolete policies instead of leaving them active and searchable. A well-governed knowledge repository is what turns Herbie.AI’s AI-RAG from a nice technical feature into consistently accurate, trustworthy answers.